White paper · Mission readiness
Readiness Is a Graph: From Local Green Status to Mission-Qualified Availability
A locally valid status does not establish that the right asset, configuration, crew, support, and time window resolve for a particular mission. This paper separates the public readiness record from a bounded Grid proposition and evaluation method.
Narrated film · 1:12
One transport disappears. Three planning views disagree.
Watch the shared model expose what changed, compare the remaining options, and leave the revised plan for an officer to approve.
An authored scenario that explains the idea. Read the story and its limits.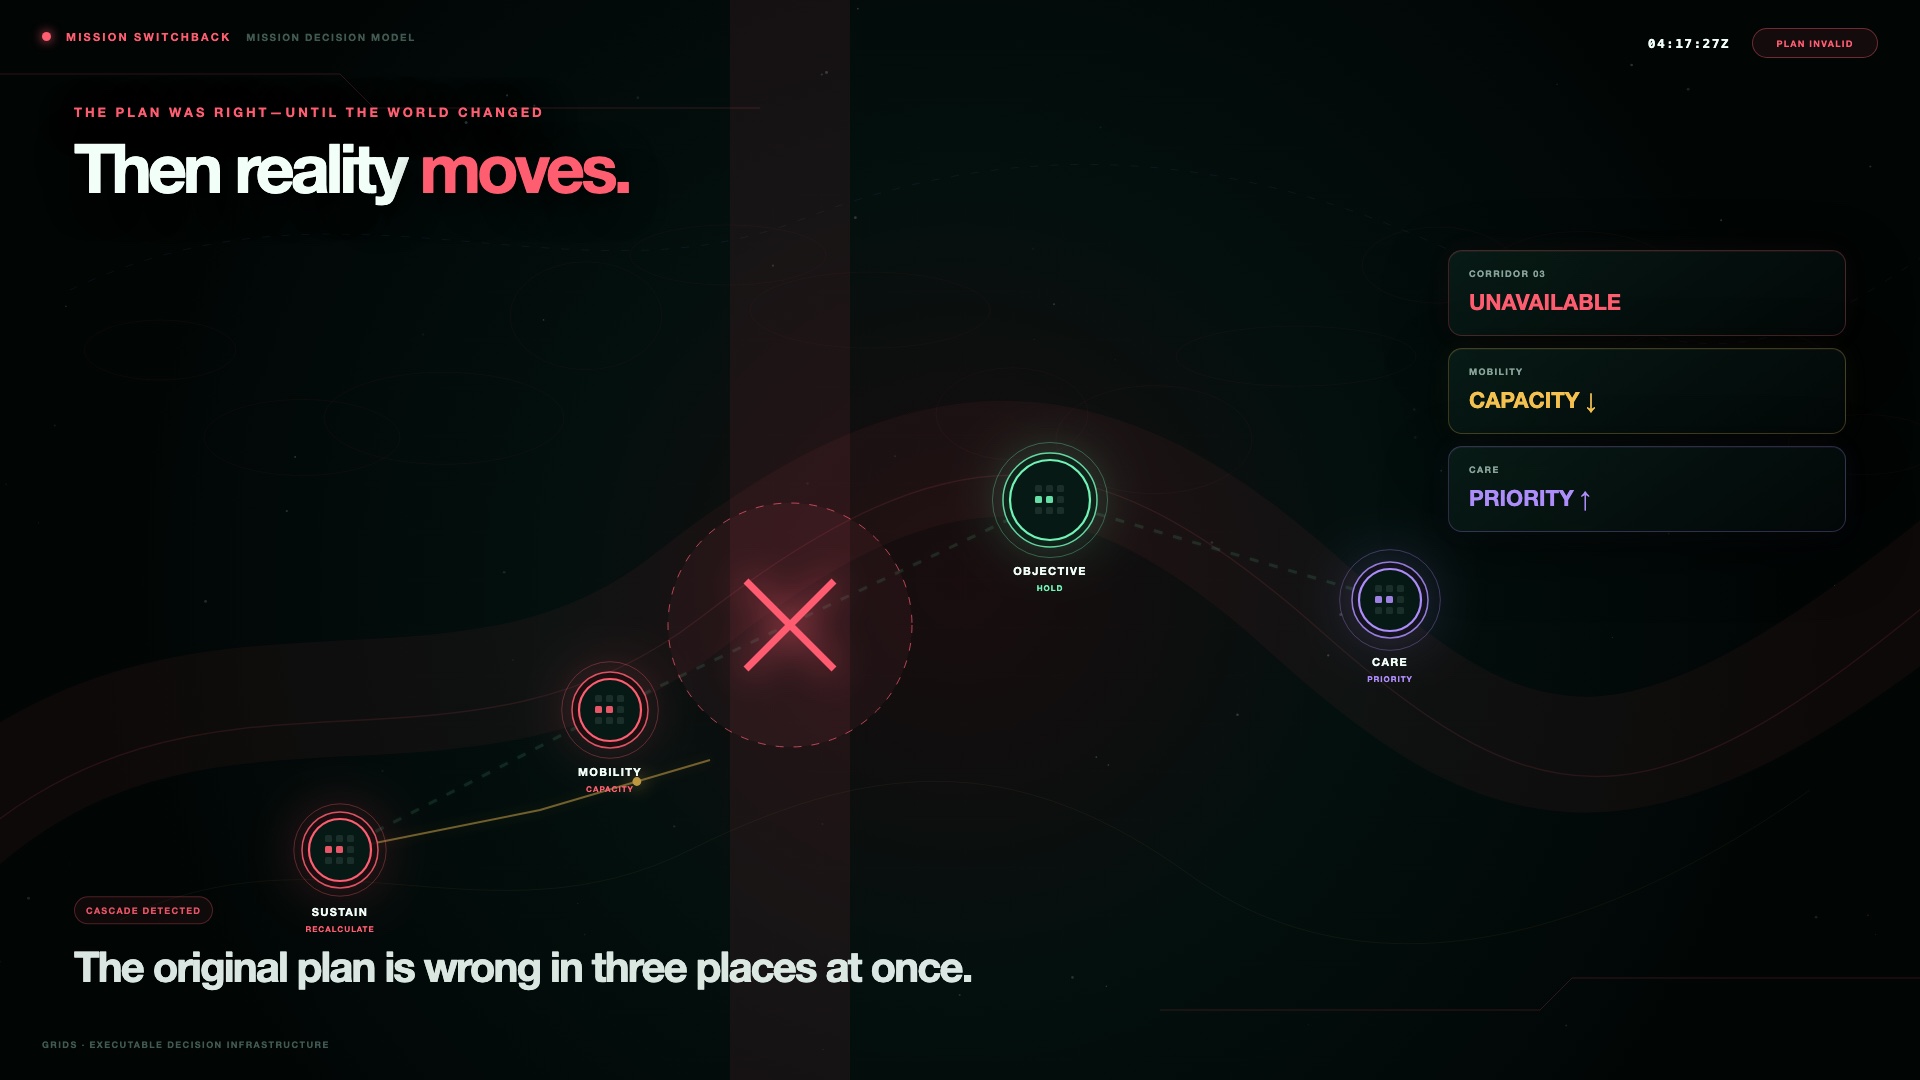 ▶ 1:12
Jump to a section in this paper
A green component is not yet a ready mission
A fleet manager sees an asset marked serviceable. A training system shows a qualified crew. A supply view reports the required support package on hand. Each status may be correct within its own scope, revision, and time. The mission can still be unready.
The asset may have the wrong configuration for the assigned task. The crew may be qualified for the platform but not current for a required condition. A critical support element may be committed elsewhere. The evidence may describe different serials or different moments. A plan that fit every constraint at 0200 may cross a duty, maintenance, fuel, or arrival window after one delay.
This is the difference between local green status and mission-qualified availability. “Local green” is used here as plain language for a source or team reporting that its own test has passed. “Mission-qualified availability” is an analytical term for a narrower conclusion: a named force or asset can support a named task, in the required configuration and condition, with eligible people and support, during a stated interval, under the applicable authority. It is not a new official readiness rating.
The institutional record treats readiness as multidimensional and mission-relative. Grid enters only as a proposition: make a specific conclusion's dependencies, evidence, and time explicit, then test the model within declared bounds.
What the public readiness record establishes
The Defense Department does not define strategic readiness as an equipment count. DoD Directive 7730.65 establishes the Defense Readiness Reporting System and calls for readiness information that supports strategic, operational, and risk analysis. Its strategic picture is informed by traditional unit-level resource and training readiness, infrastructure capability and resilience, allied and partner contributions, and threat analysis. The directive defines tactical readiness in terms of the resources and training required for a unit or force to execute its designed or assigned mission.
Army policy makes the distinction concrete. Army Regulation 220-1 derives a designed-capability C-level from four measured areas: personnel, equipment on hand, equipment readiness or serviceability, and training. It separately defines an A-level for readiness to accomplish a primary assigned mission, with manning and equipping measured against that mission's specific requirements. Commanders assess mission-essential tasks and apply professional judgment; the regulation does not reduce the official conclusion to an automatic equipment rollup.
Even familiar platform metrics require careful scope. In its review of 49 aircraft, GAO defined mission capable rate as the percentage of time an aircraft can fly and perform at least one mission. Only four of the 49 aircraft met their annual mission-capable goal in a majority of fiscal years 2011 through 2021. Program officials cited interacting sustainment challenges that included aging aircraft, maintenance, and parts or supply problems. A fleet rate is useful evidence about fleet health. It does not by itself establish that a particular tail, payload, crew, support chain, and window can execute a particular task.
The people and support edges are equally real. GAO's 2026 cross-domain readiness testimony describes shortages of adequately trained personnel, aircraft maintainers, and sailors, alongside maintenance, parts, technical-data, infrastructure, and logistical-support challenges, especially in contested environments. These findings establish why equipment status cannot stand in for the complete mission package; they do not imply that one information model can fix readiness.
Condition evidence has its own discipline. DoD Instruction 4151.22 describes Condition-Based Maintenance Plus as maintenance based on evidence of need, using sources such as inspections, maintenance and supply events, life-cycle records, and sensors. Its data scope includes configuration, reliability, availability, performance, and maintenance history. That framework is not evidence that Grid predicts failures or implements predictive maintenance.
Together, these sources support a bounded conclusion: readiness relates mission, resources, people, condition, support, and time while retaining institutional judgment. They do not prescribe Grid, validate a formula, or prove operational improvement.
Represent the conclusion as a dependency graph
A readiness report often presents an aggregate result. A readiness graph preserves its path: mission requirements, identified resources, evidence, eligibility rules, time intervals, decisions, unresolved gaps, and the dependencies among them.
For one bounded mission package, the graph should represent at least six dependency families:
- Identity: Which unit, asset, component, support item, and person does each record describe? Are identifiers, substitutions, custody, and revisions aligned, or do green systems describe different objects?
- Configuration: Does the asset carry the hardware, software, modification, payload, protection, communications, or approved substitute required for this task under the applicable baseline?
- Condition: What inspection, maintenance, fault, limitation, release, or serviceability evidence supports use? Who supplied it, when, and what makes it expire or become disputed?
- Crew: Are the required people assigned, available, qualified, current, and within represented limits for the entire task? A headcount cannot substitute for role, skill, or time eligibility.
- Support: Which fuel, power, munitions, spares, tools, maintainers, facilities, transport, data, permissions, and partner contributions are required, committed, shared, or constrained?
- Time: Do all required intervals overlap? Configuration, crew, support, departure, and completion windows can each be locally valid without intersecting.
The mission definition anchors those families. The authority boundary gates the result. Without the first, “ready” has no declared task. Without the second, a calculated finding can be mistaken for an official determination or an order.
The output should therefore be richer than green or red. Useful modeled states include qualified within the declared window, not qualified because a represented constraint fails, unresolved because required evidence is missing or contradictory, and expired because the supporting facts are no longer timely. Each state should carry the mission, source and model revisions, validity interval, binding constraints, and reasons.
The Grid proposition
Grid proposes authoring that bounded graph as a reactive computational model. Configured connectors bring named source revisions into explicit fields. Predicates encode requirements selected for evaluation. Dependency paths identify conclusions that use a changed fact, while explanation shows why a package qualified, failed, remained unresolved, or expired. Different interfaces can present the same revision for distinct roles.
That is an architecture proposition. Grid does not make a source record true, establish the correct readiness policy, or validate a commander's judgment. It does not infer unmodeled mission requirements, diagnose equipment, predict failures, certify a crew, create support capacity, or make a readiness determination. A connector is configured and tested against a named interface; integration is not automatic. A modeled status is a reviewable calculation, not an authorization or external action.
Decision Advantage visualizes the dependency pattern. The Supplies Were Already There connects identity, condition, movement, and release evidence. Every System Works. The System Does Not. shows locally valid revisions diverging. These authored fixtures are not a fielded readiness demonstration.
An illustrative mission-package change
Consider a fictional mobility detachment evaluating one night support mission. The authored fixture requires one serviceable air vehicle with configuration K-42, one qualified two-person crew, a ground-support window from 0340 to 0410, departure at 0430, and completion by 0520. The names, times, rules, and result are invented for evaluation.
At 0200, separate source views appear green:
- Fleet maintenance reports vehicle M-17 serviceable as of 0135.
- Configuration management reports K-42 installed, but its evidence packet identifies the installation event without binding it to M-17's current serialized configuration.
- Crew scheduling reports Crew C-4 qualified and available, with the represented duty interval ending at 0545.
- Ground support reports the required service team and fuel point available during the authored window.
A dashboard could display four favorable statuses. The dependency model returns unresolved because the configuration claim has not yet been tied to the selected asset. An authorized configuration source later supplies that association. The modeled package becomes qualified within the declared 0430–0520 interval, subject to review; nothing has been dispatched or approved.
Then a route fact changes. Modeled completion moves from 0520 to 0610. Vehicle serviceability, configuration, and ground-support status remain unchanged. Crew C-4 no longer covers the full task interval, so the mission package becomes not qualified under the represented crew-time rule. Only the dependent paths recalculate; the source systems do not need to turn their local statuses red for the combined conclusion to change.
The model can expose the failed edge and evaluate only the alternatives authored into the fixture, such as a different eligible crew, a different vehicle-and-crew pairing, or a changed departure. It cannot extend a duty period, waive a requirement, assign a crew, release the vehicle, or order the mission. The accountable operations and command roles decide whether to correct the evidence, select an authorized alternative, accept risk under their actual policy, defer, or cancel.
This scenario does not demonstrate real source integration, optimization, prediction, policy validity, or readiness improvement. It demonstrates the acceptance behavior a future prototype should be required to reproduce.
Authority, security, and integration remain outside the graph
An executable graph can make authority visible. It cannot confer authority. Source owners remain responsible for identity, configuration, maintenance, personnel, and support evidence. Commanders and other designated officials retain readiness assessment, risk acceptance, resource assignment, and mission authority under applicable policy. A field labeled AUTHORIZED is data; authentication, delegation, scope, and a durable external decision record must support any real authorization claim.
Readiness information is also sensitive. DoD Directive 7730.65 says readiness levels and associated reporting data should receive appropriate operations-security protection until approved for release outside DoD. A model that exchanges selected results does not decide classification, releasability, need to know, privacy, export controls, or coalition disclosure. It is not a cross-domain solution, and package signing or provenance does not make content releasable.
The complete deployed system would require security engineering, interface control, data-owner approval, identity and access management, logging, testing, and authorization in its intended environment. For DoD systems, DoD Instruction 8510.01 establishes the Risk Management Framework and system-authorization structure. Grid makes no claim here of a deployment, authorization to operate, classified accreditation, cross-domain approval, or suitability for a particular mission system.
Configured integrations must also fail visibly. A delayed feed, rejected message, stale cache, identity mismatch, changed schema, or unavailable downstream service should produce a bounded error or unresolved state, not a silently current green status. Local execution does not prove operation through denied, disrupted, intermittent, and limited communications; Grid does not provide the communications path or guarantee conflict-free reconciliation after reconnection.
A bounded evaluation that can produce evidence
Begin with one mission type, asset class, configuration baseline, small crew and support requirement set, named source owners, and one accountable reviewer. Use historical or synthetic data until another boundary is authorized. Record the current reports, calls, rekeying, exceptions, elapsed time, and authority.
Before implementation, have the responsible policy and mission owners approve the represented requirements and expected results for a controlled fixture. Include cases in which every source agrees, then seed specific failures:
- Two records refer to different serials or unit revisions.
- A required configuration is absent, superseded, or unsupported.
- Condition evidence is stale, missing, or contradicted.
- A crew is qualified but unavailable or outside a represented time limit.
- A support resource is double-committed or arrives after the window.
- One changed time moves an otherwise valid package across a threshold.
- A user attempts to qualify or execute a package without the required authority evidence.
Preserve every input snapshot, source and model revision, requirement, expected disposition, actual disposition, explanation, reviewer action, and error. Evaluate at least five groups of measures:
- Evidence integrity: records bound to the correct identity and revision; required evidence with source and observation time; stale or contradictory claims detected; unsupported qualifications. The acceptance target for seeded identity conflicts and missing required evidence should be zero unsupported qualified results.
- Dependency correctness: expected conclusions affected by each seeded change; unrelated conclusions left stable; complete reason paths for failed and unresolved states; deterministic replay against the same fixture and model revision.
- Mission discrimination: agreement with dispositions established in advance by qualified policy and mission owners; false-qualified, false-unqualified, and unresolved rates reported separately. Aggregate accuracy must not hide a dangerous false qualification.
- Decision flow: elapsed time from changed source fact to revised modeled state; manual handoffs and rekey steps; time to locate the binding dependency; conflicting revisions visible across role views. Compare with the recorded baseline without presuming improvement.
- Authority and integration behavior: attempts blocked when required authority evidence is absent; connector failures surfaced; stale inputs prevented from appearing current; reviewer decisions attributable to the correct role; downstream acknowledgments linked to the authorized revision where a test integration exists.
The evaluation owners should set thresholds before running the fixture and treat a missed safety or authority threshold as a failed evaluation, not an opportunity to redefine success. Passing supports only a product-demonstration claim for those sources, rules, cases, and operating conditions. It does not validate readiness policy, establish an ATO, or show that Grid improved readiness or mission outcomes.
A practical next step is to map one source change through the From a Changed Fact to Coordinated Action journey, compare this readiness question with Inventory Is Not Availability, and record the boundary in the decision evaluation worksheet. Grid Developers provides implementation-oriented guidance for explaining and validating a changing decision.
Readiness is not the color of the last system someone opened. It is a time-bounded conclusion about a mission and the evidence, resources, people, support, and authority on which that mission depends. The graph does not make the force ready. It makes the proposed path to a readiness conclusion explicit enough to inspect, challenge, and evaluate.
Related films, scenarios, and next steps
Continue exploring
Follow the next question.
From Common Operating Picture to Common Operating Model
Seeing the same facts is not the same as calculating from the same rules. A common operating model connects source identity, dependencies, constraints, alternatives, authority, role-specific views, and replayable evidence.
Understand · EvaluateSource-grounded ExploreHow Grid Works: From Typed Facts to Accountable Action
A technical and operational guide to the six-stage Grid chain: governed sources, a shared and versioned model, reactive constraint evaluation, coordinated surfaces, explanation and evidence, and AI assistance bounded by human authority.
Understand · EvaluateSource-grounded ExploreCourse-of-Action Feasibility Without the Slide-Deck Reconciliation Cycle
A course of action remains feasible only while its facts, assumptions, resources, timing, constraints, and authority remain aligned. This paper separates the public planning record from a bounded Grid proposition for keeping that conclusion inspectable as conditions change.
Understand · PlanSource-grounded Explore